

When to use it
The embedded
task-graph skill teaches the model this ruler, the plan schema and the discipline (“you never declare done”).
You don’t have to ask for it by name. A substantial task (complexity ≥ 6) is auto-routed here by default — see Plan-and-Solve → Routing to the task graph. The routing steers, it doesn’t force: genuinely serial or small work still runs directly.
The plan schema
One JSON object describes the whole delivery:depsmay only reference tasks declared earlier (which also rules out cycles).promptmust be self-contained — workers do not see the conversation.#<depID>is replaced with that dependency’s output.validation[].runcommands are executed by the engine (inheriting the coder sandbox and the unsafe-command denylist) — never by the executor.expectis prose for the reviewer. A bare string is a prose-only contract (reviewer verifies by inspection).agentdefaults tocoder(any squad worker type works);max_attemptsdefaults to 3;require_reviewdefaults to true, per graph or per task.toolsoptionally grants the task’s executor worker session plugins —"tools": ["@browser", "@websearch"]. The reviewer never receives them. See Worker capabilities below.
Execution: ready-set scheduling
Tasks fire the moment their dependencies complete — no level barriers, no wasted wall-clock. Concurrency is capped by the squad’s existingCHATCLI_AGENT_MAX_WORKERS knob (the graph’s own max_parallel can lower it); no new environment variables were added for this feature.
Each task runs through an attempt loop:
- Checkpoint — a shadow-git snapshot of the workspace, best-effort, before the executor starts.
- Executor — a fresh worker receives the prompt (plus reviewer feedback on retries).
- Gate — the engine runs every
validation[].runcommand itself and records output; a non-zero exit fails the attempt without spending a reviewer. - Review — a fresh
reviewerworker (read-only tools) receives the contract, the gate outputs and the executor’s report, and must end withVERDICT: PASS — evidenceorVERDICT: FAIL — what is missing. - Promote or retry — gate green + PASS promotes to
donewith the evidence recorded; FAIL retries with the feedback injected, up tomax_attempts, then the task fails and its successors becomeblocked.
pending → running → reviewing → done | failed | blocked.
Every attempt also carries its real cost: each worker LLM call is attributed to the graph node that spawned it, using the same per-call accounting as cost tracking.
Surfaces
@taskgraph (for the AI)
File first for real graphs. Inline
graph args beyond ~2KB get truncated by output-token limits (“unexpected end of JSON input”). The reliable form is two calls: write the plan JSON with @coder write, then run with file — the file may hold the bare plan, {"graph":{...}} or the full envelope. The embedded skill teaches the model exactly this.run executes the whole graph in a single tool call, streaming events as they happen. Resume is inherent: completed tasks stay done, so re-running a failed graph continues where it stopped.
/taskgraph (for humans)
/taskgraph is allowlisted as a mid-run side command — type it while the graph executes to inspect progress without touching the orchestrator loop.
The live dashboard
This dashboard goes deep on one task graph run. To watch the whole runtime live (every agent, LLM request, tool, skill, MCP server, pattern and background job, across processes), use
/dash; task graph runs show up there too./taskgraph dash (or {"cmd":"dash"}) serves a browser dashboard from an ephemeral 127.0.0.1 port — a single embedded file, zero CDN, zero configuration:
- Animated DAG canvas — phase swimlanes, dependency béziers with animated dashes into running tasks, status-colored cards with attempt count and per-task cost; drag to pan, ctrl/⌘+wheel to zoom,
0to fit, lineage highlight on hover. - Evidence popovers — click a task for its prompt, validation contract, gate outputs, reviewer verdict + evidence and the executor/reviewer run IDs.
- Results tab — critical path, wall-clock vs agent time, parallelism factor and the real cost per task.
- Live — the page polls the persisted state every second and tails the event feed.
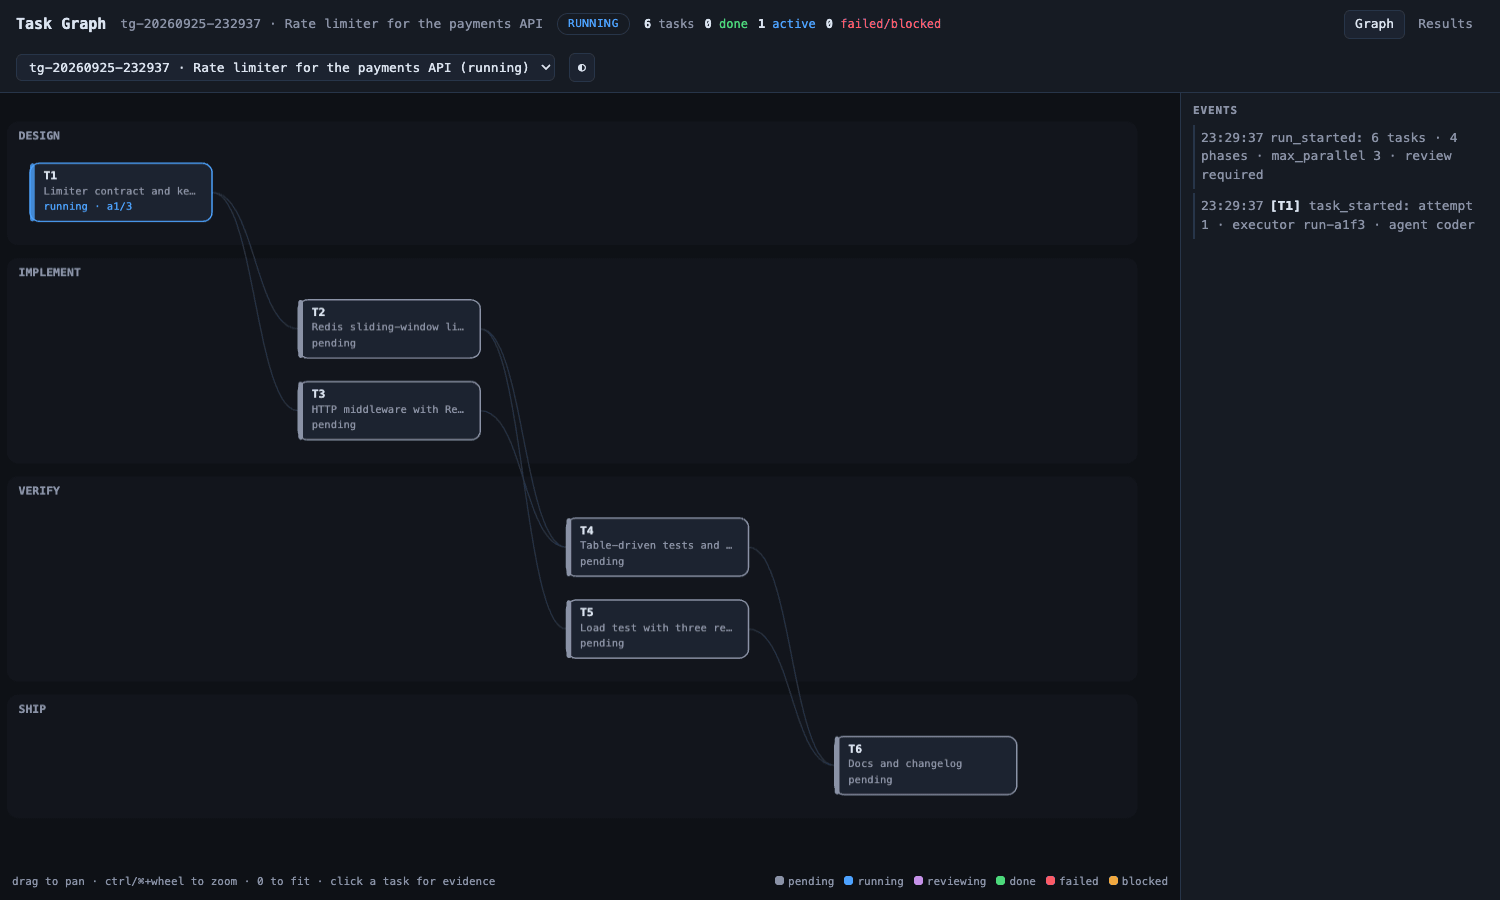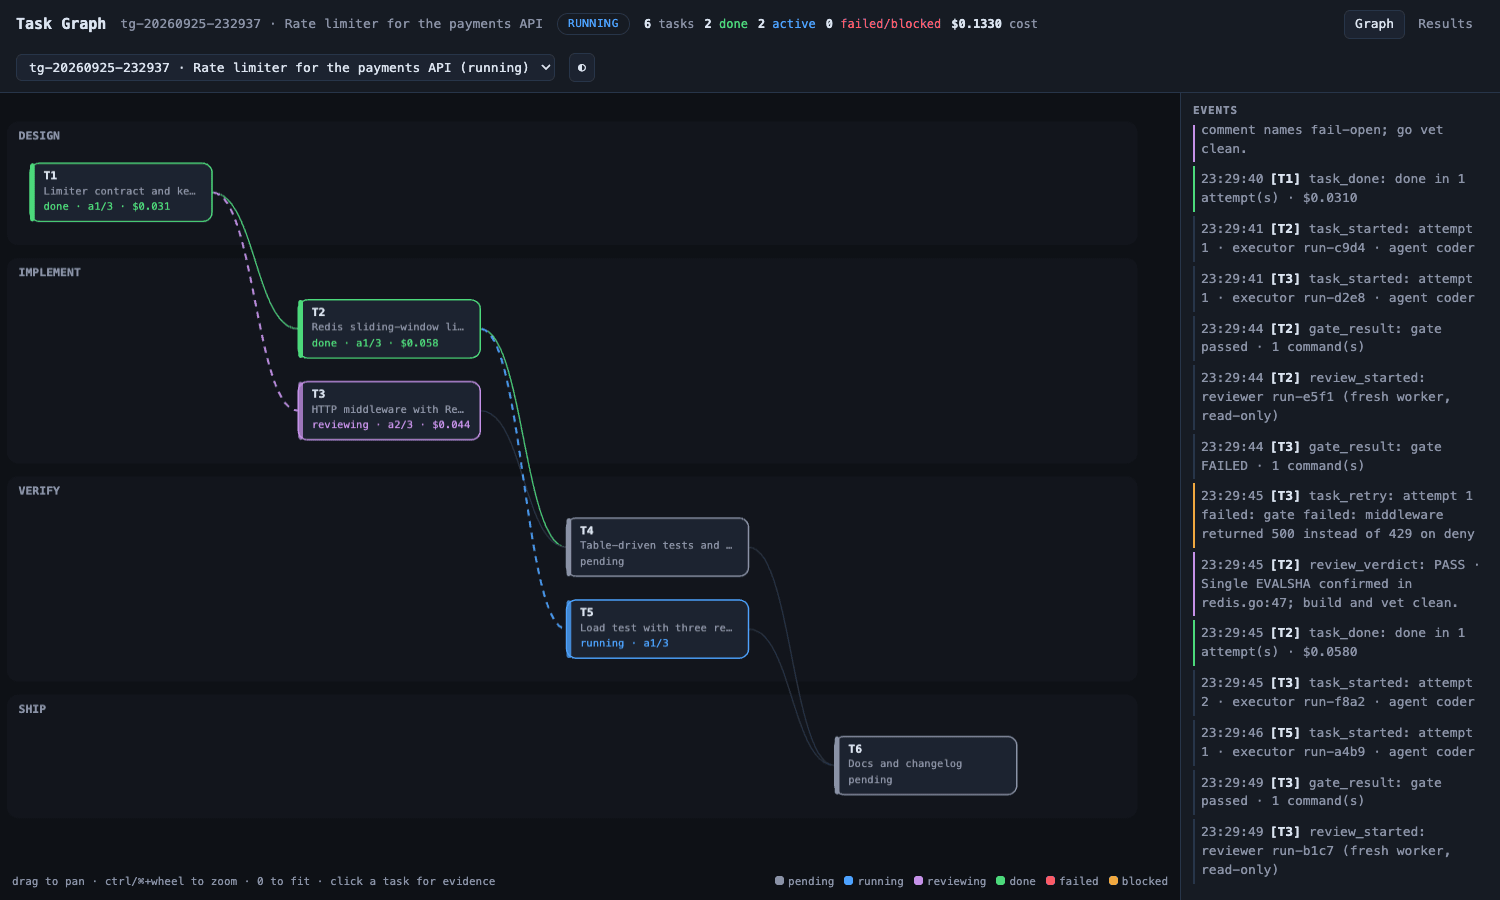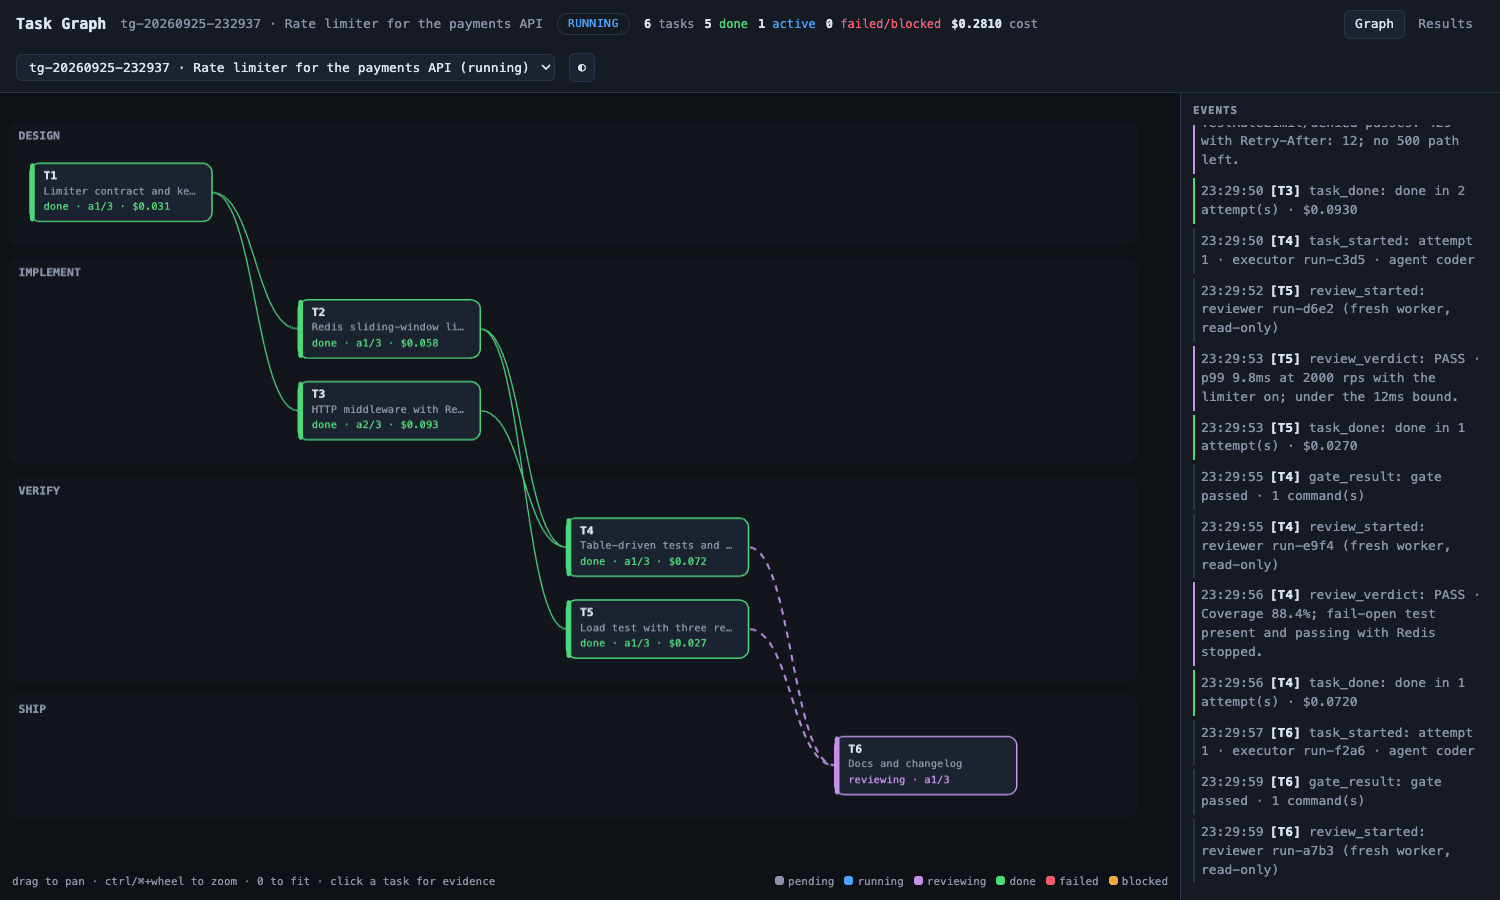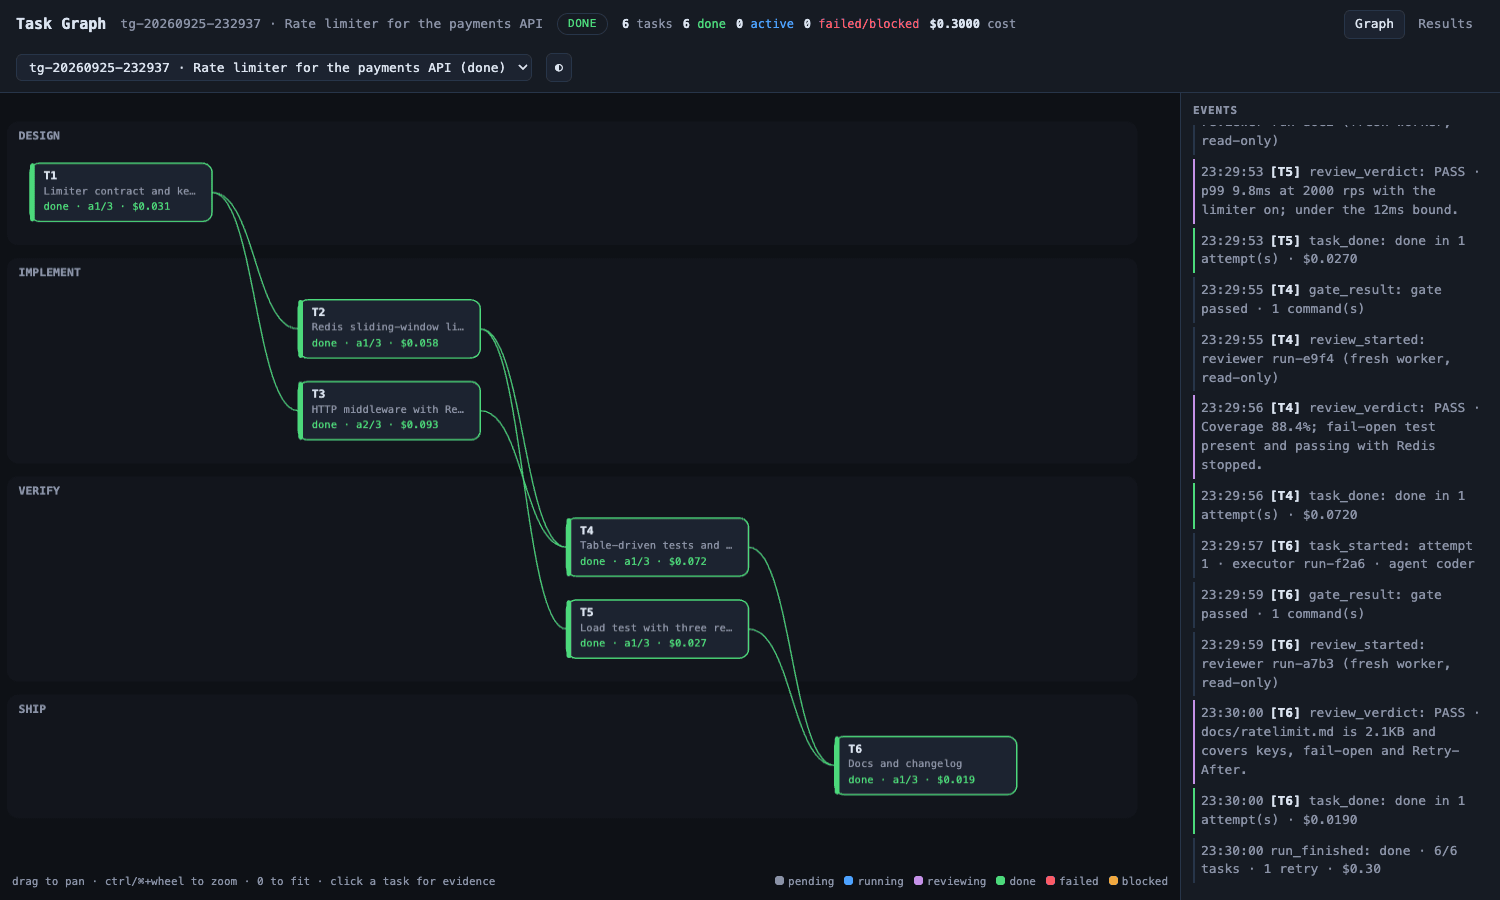
The same run from start to finish: tasks light up as the ready set advances, a gate failure sends a task back for a second attempt, a click opens its evidence with both attempts, and the Results tab sums critical path, times and cost. (Synthetic data.)
state.json and events.ndjson from disk on every request. Closing the dashboard never affects a run, and finished runs render just as well.
Worker capabilities
Each executor and reviewer runs with the session’s own context — proactive memory/session recall, CCR expansion of truncated results, and read-only memory/session/knowledge tools — so a worker picks up what the session already learned instead of starting blind. Beyond that, two capabilities are opt-in per task:- Tool grants.
"tools": ["@browser", "@websearch"]on a task gives its executor those session plugins (builtins ormcp_*), gated by the same security policy — a@browser clickprompts exactly as it would in/coder. The reviewer never gets tools (its job is inspection).@browserdrives one shared page, so grant it to a single task at a time; parallel browser tasks would corrupt each other’s element refs. - User skills. A worker’s task text is matched against your own skills the same way the orchestrator matches them: pinned skills always apply, trigger-matched ones are injected (capped and budgeted). Your curated knowledge reaches every executor.
Persistence
Each run owns~/.chatcli/taskgraph/<runID>/:
The store is bounded: runs older than 30 days are pruned automatically on the session’s first store access (age = last state write), and
prune cleans up on demand — Go durations (72h), day suffixes (30d) or all. The active run is never removed.
Runs appear in /agents (and the Conversation Hub) as a parent run with each executor and reviewer registered as children — cancellation propagates down the tree.